Model Gallery

663 models from 1 repositories

Filter by type:

Filter by tags:

ternary-bonsai-2-27b
Ternary Bonsai 2 27B (PrismML) is a 27B-class reasoning model with ternary transformer weights. This PTQ1_0 build packs the trits densely at 1.75 bits per weight (5.95 GB) and includes the Q8_0 vision projector. PTQ1_0 is a Prism-private GGUF type, so the entry uses the bonsai backend (PrismML's llama.cpp fork) instead of stock llama.cpp.

Repository: localaiLicense: apache-2.0

swift-qwen3.8-27b
Swift-Qwen3.8-27B is UkisAI's reasoning-efficient fine-tune of Qwen3.8-27B. The publisher reports 58.3% fewer thinking tokens with less than 1% quality loss. This Q4_K_M GGUF includes the F16 vision projector and enables MTP speculative decoding. The weights use the Swift Open License v1.0.

Repository: localaiLicense: swift-open-license-1.0
spark-x2.5-4b
# Spark-X2.5 [](https://join.slack.com/t/tokenspark/shared_invite/zt-432qf8l2f-5~dLyXv8uETr0P0UuC07nw) [](https://discord.gg/kTDE2Hg8aw) [](https://www.youtube.com/@SparkLLM) [](https://dev.to/sparkllm) [](https://bsky.app/profile/sparkllm.bsky.social) [](https://x.com/sparkllm) [](https://www.zhihu.com/people/zhiikz7qh7m) [](images/xhtoken-wechat.jpg) > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. ## Introduction We are introducing Spark-X2.5-4B and Spark-X2.5-1.7B, two compact, general-purpose language models designed to make capable AI more practical, efficient, and accessible. The models deliver strong performance across a broad range of everyday tasks—including conversation, writing, translation, reasoning, coding, tool use, and agentic workflows—achieving leading results among open-source models of comparable size. Spark-X2.5 combines an efficiency-oriented architecture with native context windows of up to 1M tokens, and support for more than 200 languages. ...

Repository: localaiLicense: apache-2.0
qwen3.8-flash-next-uncensored
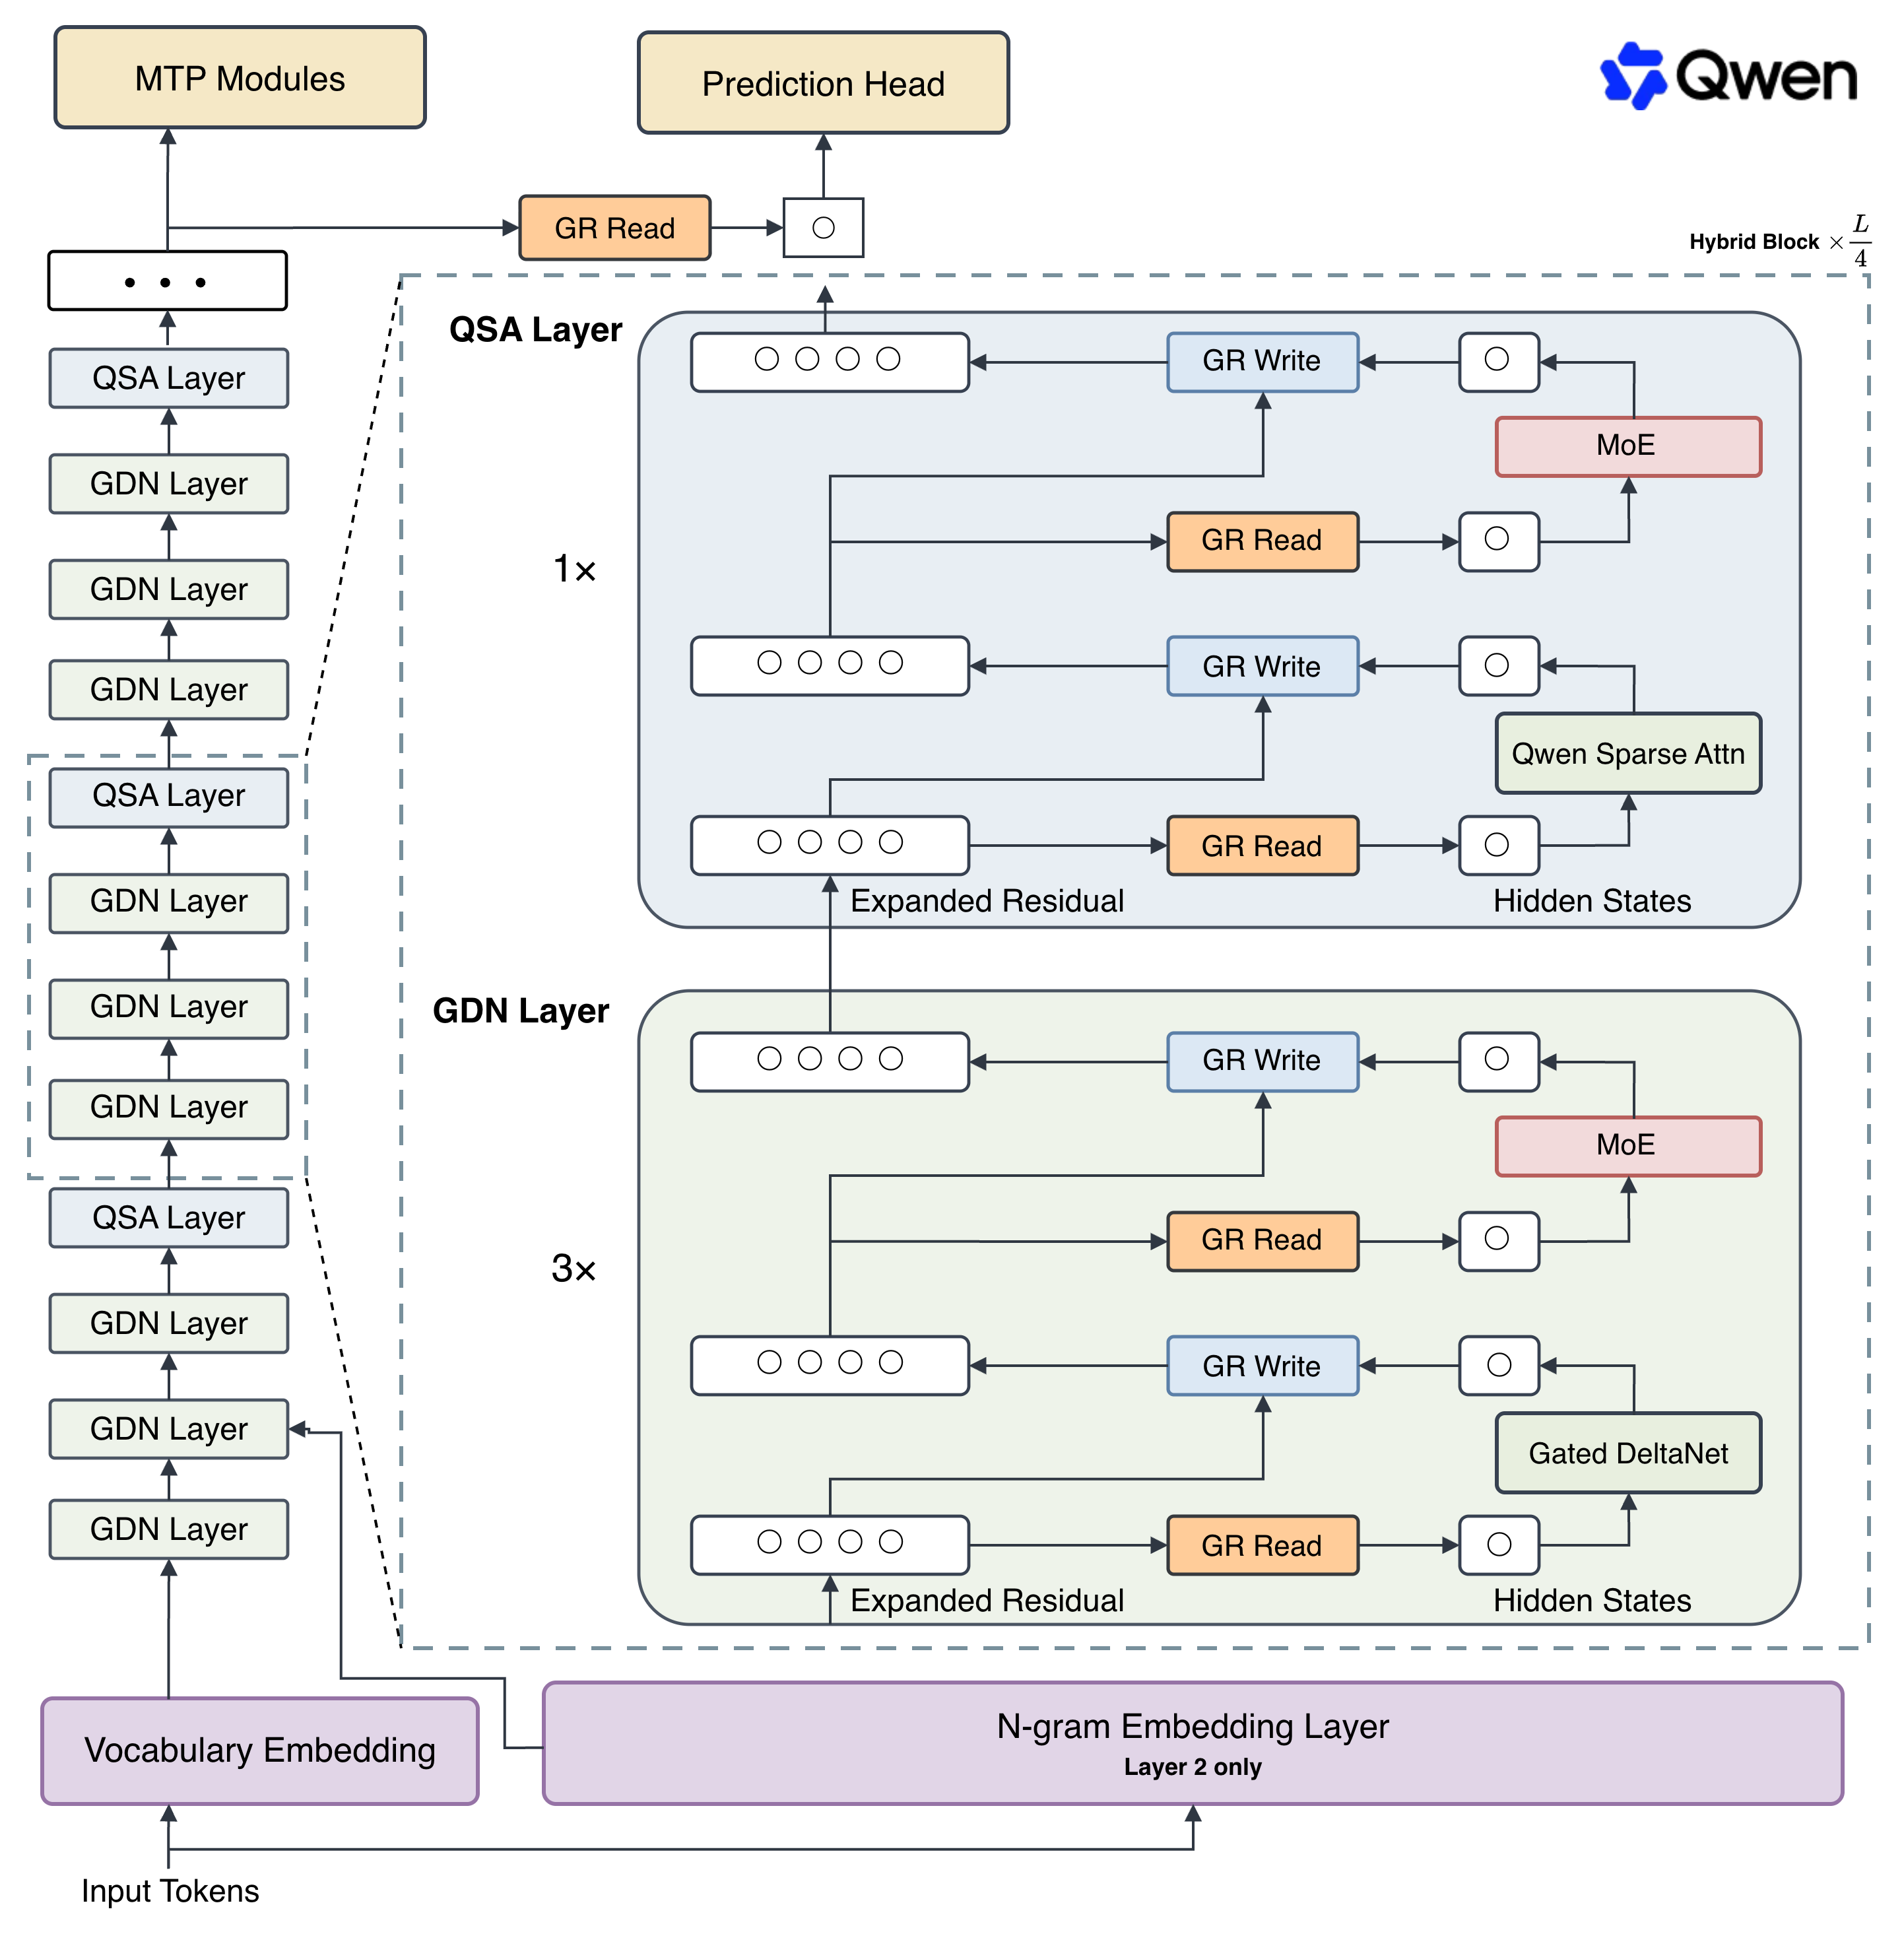
# Qwen3.8-Flash-Next > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. > > These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc. > [!Tip] > For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud. > > In particular, **Qwen3.8-Flash** is the official version based on Qwen3.8-Flash-Next with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-Flash Overview. As the frontier of foundation models pushes toward ever-larger parameter counts and ever-longer context windows, the question is no longer just how much we can scale, but how efficiently we can do so. Sustainable progress toward artificial general intelligence (AGI) that benefits everyone demands architectural innovation. Today, we are sharing a concrete step in that direction: Qwen3.8-Flash-Next. ...

Repository: localaiLicense: apache-2.0

deepseek-v4-flash-vision-exp
# DeepSeek-V4-Flash-Vision-Exp ## Introduction We are excited to introduce **DeepSeek-V4-Flash-Vision-Exp**, our first experimental multimodal model in the DeepSeek-V4 family. It builds on the DeepSeek-V4-Flash architecture by incorporating visual modules and undergoing continued training to unlock visual understanding capabilities. Compared to DeepSeek-V4-Flash-0731, DeepSeek-V4-Flash-Vision-Exp achieves substantial improvements on its multimodal agent capabilities, while maintaining comparable performance on text-only agent tasks. Notes: 1. For the text agent benchmarks above, DeepSeek models are evaluated with the minimal mode of DeepSeek Harness as the agent framework, using the `max` reasoning effort level with `temperature = 1.0, top_p = 0.95`. 2. † For ApexBench and Agents' Last Exam, DeepSeek-V4-Flash-0731 ignores the multimodal elements in the input. ## Repository layout This repository contains the tokenizer, prompt encoding reference, and a minimal PyTorch inference implementation for DeepSeek-V4 Flash Vision. The reference inference covers the vision encoder and aligner, DFlash attention, MoE, Hyper-Connections, and the DSpark forward path. ...

Repository: localaiLicense: mit

qwopus3.8-27b-flash-v2
Qwopus3.8-27B-Flash-V2 is a new post-training release for reasoning and agent workloads. This Q4_K_M GGUF includes the F32 vision projector and uses llama.cpp's embedded chat template with MTP speculative decoding.

Repository: localaiLicense: apache-2.0

qwopus3.8-27b-flash-v2-q8
Qwopus3.8-27B-Flash-V2 is a new post-training release for reasoning and agent workloads. This Q8_0 GGUF includes the F32 vision projector and uses llama.cpp's embedded chat template with MTP speculative decoding.

Repository: localaiLicense: apache-2.0

qwopus3.8-27b-flash
Qwopus3.8-27B-Flash is a Qwen3.8-27B fine-tune for reasoning and agent workloads. This Q4_K_M GGUF includes the F32 vision projector and uses llama.cpp's embedded chat template with MTP speculative decoding. The publisher reports a known Python code indentation issue.

Repository: localaiLicense: apache-2.0

qwopus3.8-27b-flash-q8
Qwopus3.8-27B-Flash is a Qwen3.8-27B fine-tune for reasoning and agent workloads. This Q8_0 GGUF includes the F32 vision projector and uses llama.cpp's embedded chat template with MTP speculative decoding. The publisher reports a known Python code indentation issue.

Repository: localaiLicense: apache-2.0

thinkingcap-qwen3.8-27b
ThinkingCap is a 27B Qwen3.8 fine-tune trained to reduce reasoning tokens, with text and image input. This Q4_K_M GGUF build uses llama.cpp, the embedded chat template, and the F16 vision projector. Licensed under PolyForm Small Business 1.0.0 with the publisher's personal-use grant; see the model license for permitted use.

Repository: localaiLicense: polyform-small-business-1.0.0

thinkingcap-qwen3.8-27b-q8
ThinkingCap is a 27B Qwen3.8 fine-tune trained to reduce reasoning tokens, with text and image input. This Q8_0 GGUF build uses llama.cpp, the embedded chat template, and the F16 vision projector. Licensed under PolyForm Small Business 1.0.0 with the publisher's personal-use grant; see the model license for permitted use.

Repository: localaiLicense: polyform-small-business-1.0.0

qwen3.8-27b-turbo-fable-cold-fusion-735-882-heretic-uncensored-neo-coder-max-mtp
RELEASE #1 GGUFS [including detailed notes, how to use, benches and much more]: https://huggingface.co/DavidAU/Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NEO-CODER-MAX-MTP-GGUF Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NM-DAU (release #1, others pending...) ( repo has 10+ other versions (and 3 branches) noted below that EXCEED the performance of all QWEN 27B models, including fine tunes. ) First, special thanks to Nightmedia for working on the first three stages prior to heretic'ing/post staging and benching everything (3 sections below). A number of my finetunes - both released and non-released - were used here as well as some third parties. Full details will be disclosed upon final release as the project shores up. THREE example generations [snippets] from STAGE1-PART2, STAGE1b-PART2 and STAGE2-rplus2 at the bottom of the page. Release(s) will be GGUFS first (linked here directly) then source code shortly thereafter [now released/open]. Some additional work and/ spawning of new branches from branch(es) below is still going on. NEW: Branch 3 added, see below. COMPLETED AND PENDING RELEASES: ...

Repository: localaiLicense: apache-2.0

apodex-1.1-mini-q4
Apodex-1.1-mini is an Apache-2.0 Qwen3.5 mixture-of-experts model for long-horizon research, data analysis, coding, file work, and tool use. It activates about 3B of its 35.95B parameters per token and supports text and image input with a context window of 262K tokens. This default entry uses the recommended Q4_K_M GGUF and F16 vision projector. An MTP-enabled build and a higher-quality Q8_0 model are available as variants.

Repository: localaiLicense: apache-2.0

apodex-1.1-mini-q4-mtp
Apodex-1.1-mini with MTP speculative decoding enabled on the recommended Q4_K_M GGUF. The model carries its native MTP head, so it needs no separate draft model. The F16 vision projector supports multimodal prompts.

Repository: localaiLicense: apache-2.0

apodex-1.1-mini-q8
Apodex-1.1-mini in the higher-quality Q8_0 GGUF format, with the shared F16 vision projector for multimodal prompts.

Repository: localaiLicense: apache-2.0

glm-5.3-flash-q4
GLM-5.3-Flash is Z.ai's natively multimodal 320B-parameter mixture-of-experts model with 18B active parameters. It combines sparse and linear attention for coding, agentic work, tool use, vision, and long-context tasks. This entry uses the UD-Q4_K_XL GGUF quantization and enables the model's MTP speculative-decoding head.

Repository: localaiLicense: mit

glm-5.3-flash-q8
GLM-5.3-Flash is Z.ai's natively multimodal 320B-parameter mixture-of-experts model with 18B active parameters. It combines sparse and linear attention for coding, agentic work, tool use, vision, and long-context tasks. This entry uses the higher-quality Q8_0 GGUF quantization and enables the model's MTP speculative-decoding head.

Repository: localaiLicense: mit

llm-jp-4-33b-thinking-q4
LLM-jp-4-33B-thinking is an Apache-2.0 Japanese and English reasoning model from Japan's National Institute of Informatics. Its dense Llama architecture has 33 billion parameters and a 65K-token context window. The model was aligned with supervised fine-tuning and DPO for multi-turn conversation and instruction following. This default entry uses the 20.2 GB Q4_K_M GGUF. The official 66.4 GB BF16 weights are available as a higher-fidelity variant.

Repository: localaiLicense: apache-2.0

llm-jp-4-33b-thinking-bf16
LLM-jp-4-33B-thinking in the official 66.4 GB BF16 GGUF format. This variant preserves the original model precision for hosts with enough memory.

Repository: localaiLicense: apache-2.0

qwen3.8-flash-next-q4
Qwen3.8-Flash-Next is Qwen's 125B-parameter, 6B-active experimental vision-language mixture-of-experts model. It targets agentic coding, reasoning, tool use, and long-context workloads with a native 262K-token context window. This default entry uses Unsloth's UD-Q4_K_XL GGUF and BF16 vision projector. Linked variants offer Q8_0 and AtomicChat's smaller IQ4_XS and Q4_K_M builds with a separate n-gram table shard.

Repository: localaiLicense: other

qwen3.8-flash-next-q8
Qwen3.8-Flash-Next in the higher-quality Q8_0 GGUF format, with the shared BF16 vision projector. This build preserves more model quality but needs more memory than the default Q4 variant.

Repository: localaiLicense: other

Page 1