Model Gallery

294 models from 1 repositories

Filter by type:

Filter by tags:

ornith-1.5-9b-uncensored
# Ornith-1.5-9B-uncensored An **abliterated** (refusal-direction-ablated) build of `ornith-ai/Ornith-1.5-9B`, produced with ZeroFuse and published by junafinity. This is the **9B control checkpoint** (bf16). Mac users should start from the MLX-8bit or GGUF-8bit siblings. The official 9B base has **no `mtp.*` tensors**; nothing was grafted. **Vision tower and MTP heads are preserved** — see Vision & MTP preservation for the before/after audit. ## Intended use: red teaming and defensive cybersecurity research These uncensored (abliterated) weights are built as a **research instrument** for red teaming and defensive cybersecurity work. Safety training suppresses the *display* of capability, not capability itself. A refusal tells you the model declined. It does not tell you whether the weights could have complied. That conflation underestimates the true ceiling and hides holes in *your* filters, classifiers, and policy layer. Use each uncensored checkpoint as the **treatment half of a controlled pair** against its original base model: ...

Repository: localaiLicense: apache-2.0
qwen3.8-flash-next-uncensored
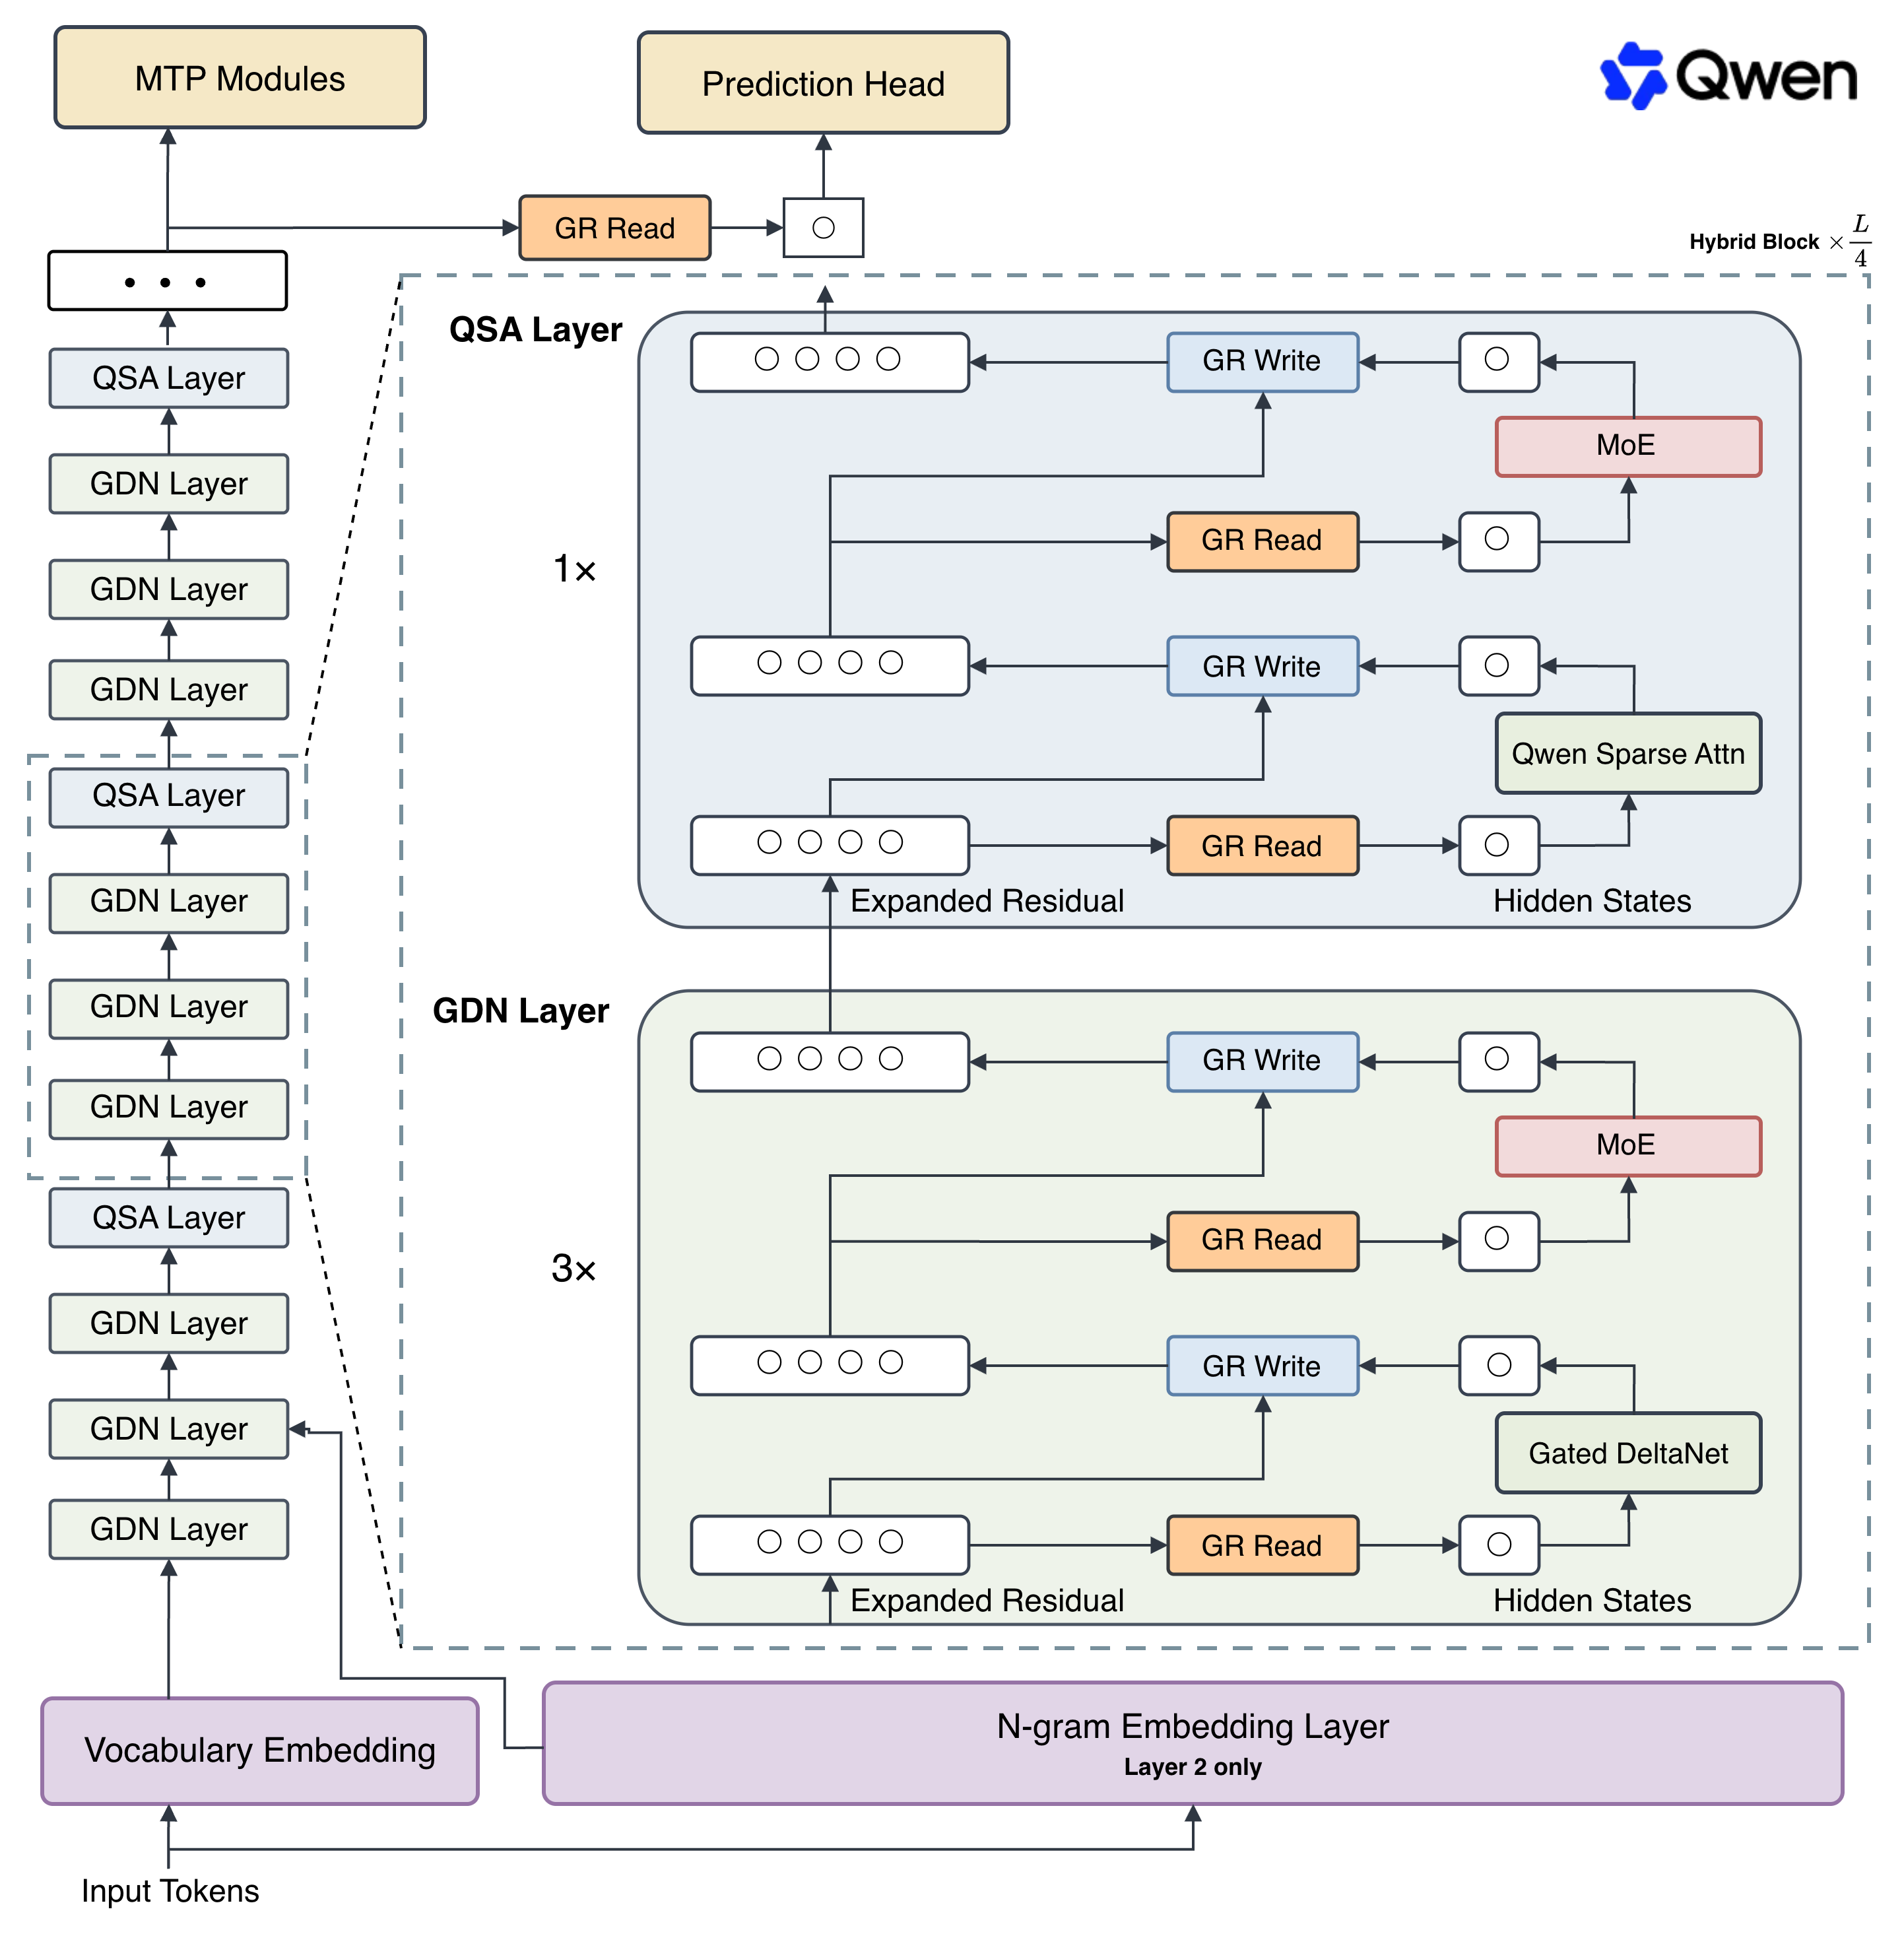
# Qwen3.8-Flash-Next > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. > > These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc. > [!Tip] > For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud. > > In particular, **Qwen3.8-Flash** is the official version based on Qwen3.8-Flash-Next with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-Flash Overview. As the frontier of foundation models pushes toward ever-larger parameter counts and ever-longer context windows, the question is no longer just how much we can scale, but how efficiently we can do so. Sustainable progress toward artificial general intelligence (AGI) that benefits everyone demands architectural innovation. Today, we are sharing a concrete step in that direction: Qwen3.8-Flash-Next. ...

Repository: localaiLicense: apache-2.0
glm-5.3-flash
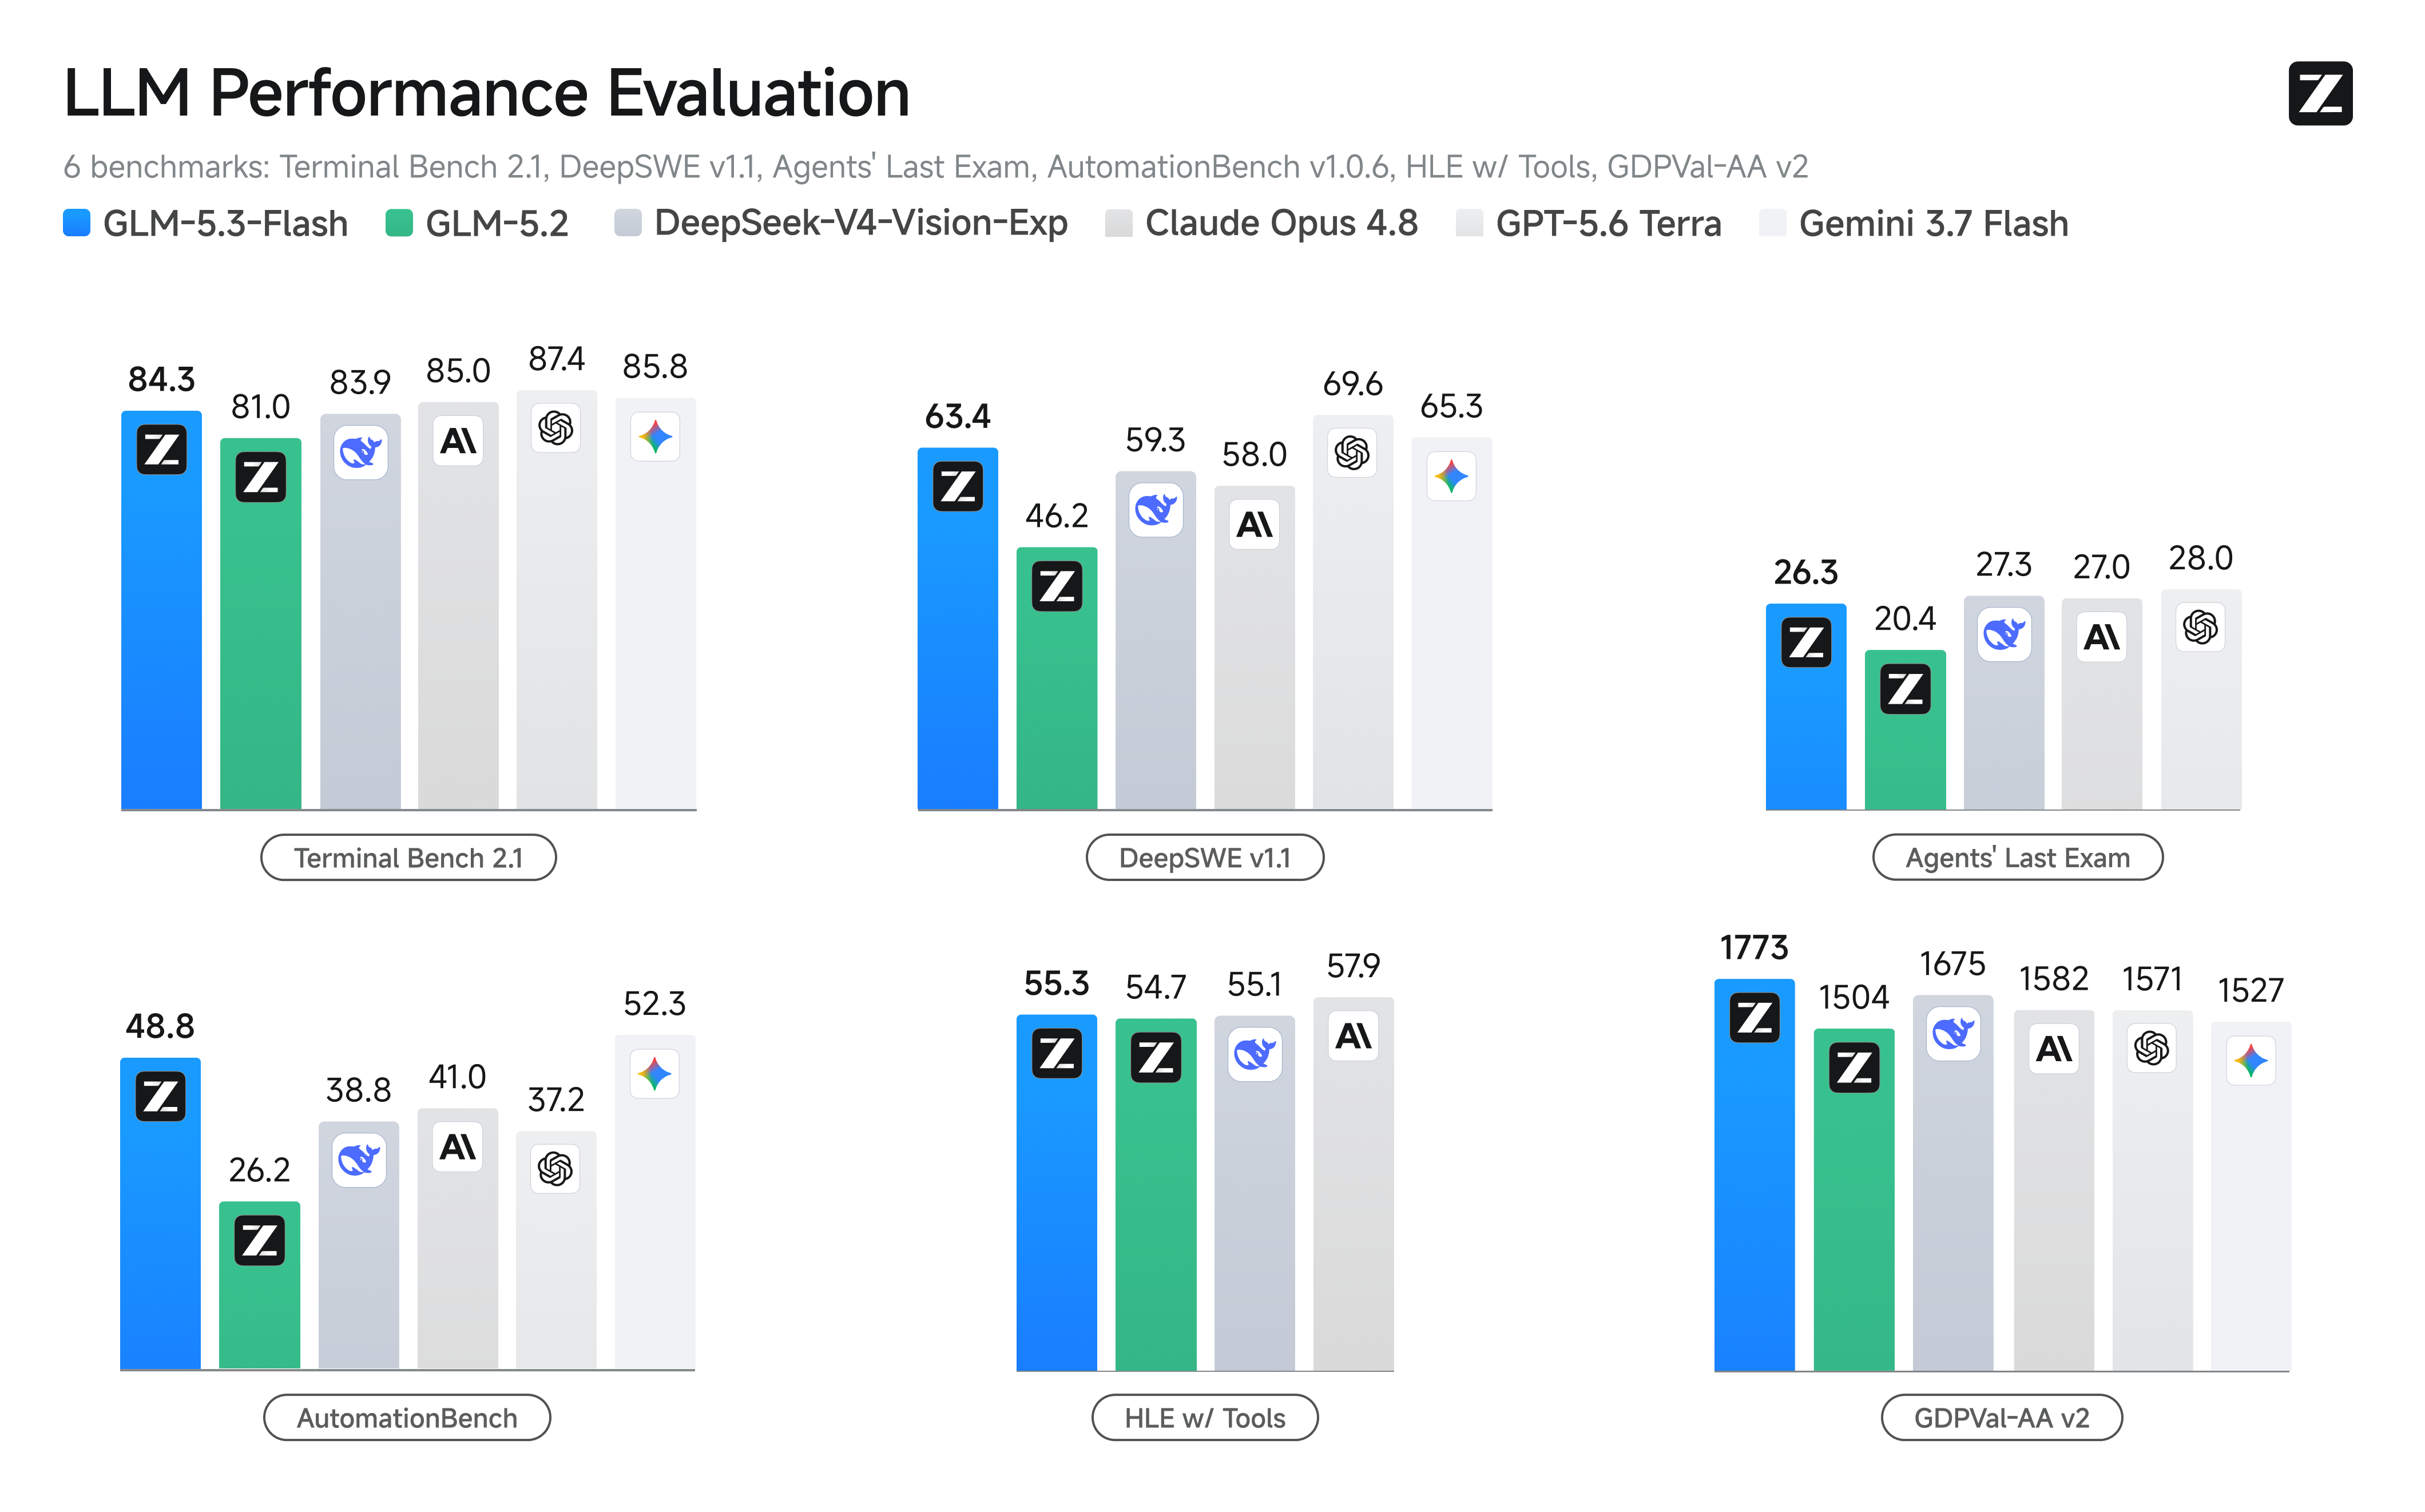
# GLM-5.3-Flash 👋 Join our WeChat or Discord community. 📖 Check out the GLM-5.3-Flash blog and GLM-5 Technical report. 📍 Use GLM-5.3-Flash API services on Z.ai API Platform. ## Introduction We introduce GLM-5.3-Flash, the first natively multimodal model in the GLM-5 series. With 320B total parameters and just 18B active parameters, it outperforms GLM-5.2 across benchmarks and real-world workloads at one-tenth the price, while approaching Claude Opus 4.8 on coding and agentic benchmarks. GLM-5.3-Flash starts from a newly trained base model, with its architecture and training recipe redesigned around capability and efficiency. For the first time in the GLM series, we introduce a hybrid architecture combining sparse and linear attention, sharply reducing long-context serving costs while preserving precise long-context capabilities. The model also adopts Manifold-Constrained Hyper-Connections (mHC) to further improve scaling efficiency. Together with our latest 30T-token multimodal pre-training corpus, these changes enable GLM-5.3-Flash to deliver more intelligence with less compute. ## Serve GLM-5.3-Flash Locally ...

Repository: localaiLicense: mit

glm-5.3
# GLM-5.3 GLM-5.3 uses the same base model as GLM-5.2 — every gain comes from post-training. Compared with GLM-5.2, it is much better at complex coding and long-horizon tasks: + Stronger Coding: GLM-5.3 is the most capable open-weights model for coding, with a 50% improvement over GLM-5.2 on our in-house Z.ai Code Bench. It also achieve open-source SOTA on public benchmarks including Terminal Bench 3.0 and Agents' Last Exam. + Emergent Cyber Capability: As we scaled post-training, cyber capability developed faster than we expected. GLM-5.3 is state of the art on CyberGym for vulnerability discovery, and its gains are largest further up the exploitation chain, where it more than doubles GLM-5.2 on exploitation benchmarks. ## Benchmark ### Serve GLM-5.3 Locally GLM-5.3 supports deployment with the following frameworks. Feel free to try them out: - SGLang — see cookbook - vLLM — see recipes - TokenSpeed — see here - Transformers — see transformers docs - KTransformers — see tutorial - Unsloth — see guide - For deployment on the `Ascend NPU` platform, inference frameworks such as vLLM-Ascend, xLLM and SGLang are supported — see here. ### Note ...

Repository: localaiLicense: other

qwen3.8-27b-uncensored-q4
Qwen3.8-27B-Uncensored reduces refusal behavior while retaining the base model's text, vision, reasoning, and tool-use capabilities. Its integrated MTP head supports speculative decoding without a separate draft model. This default entry uses the Q4_K_M GGUF and F16 vision projector. A higher-quality Q8_0 model is available as a variant.

Repository: localaiLicense: apache-2.0

cyber-tiel-coder-35b-a3b-q4-mtp
Cyber-Tiel-Coder is a 35B mixture-of-experts coding model with 3B active parameters, based on Huihui's abliterated Ornith-1.5. This UD-Q4_K_XL build includes MTP speculative decoding, the embedded Sharp chat template, and a BF16 vision projector.

Repository: localaiLicense: mit

cyber-tiel-coder-35b-a3b-q8-mtp
Cyber-Tiel-Coder is a 35B mixture-of-experts coding model with 3B active parameters, based on Huihui's abliterated Ornith-1.5. This UD-Q8_K_XL build includes MTP speculative decoding, the embedded Sharp chat template, and a BF16 vision projector.

Repository: localaiLicense: mit

twil-lm3-q4
TwIL-LM3 is a 3B SmolLM3-based reasoning model specialized for formal logic, entailment, semantic parsing, and Lean formalization. This default entry uses the publisher's recommended Q4_K_M GGUF and supports a 65K-token context window. A higher-quality Q8_0 build is available as a variant.

Repository: localaiLicense: webai-non-commercial-license-ver.-1.0

qwen3.8-35b-a3b-distill-q4
Empero's Qwen3.8 distillation into Qwen3.6-35B-A3B has 35B total parameters and about 3B active per token. This Q4_K_M GGUF build uses the embedded reasoning template and includes the F16 vision projector. Vision is inherited from the base and was not evaluated by the publisher.

Repository: localaiLicense: apache-2.0
qwen3.8-35b-a3b-distill-q5
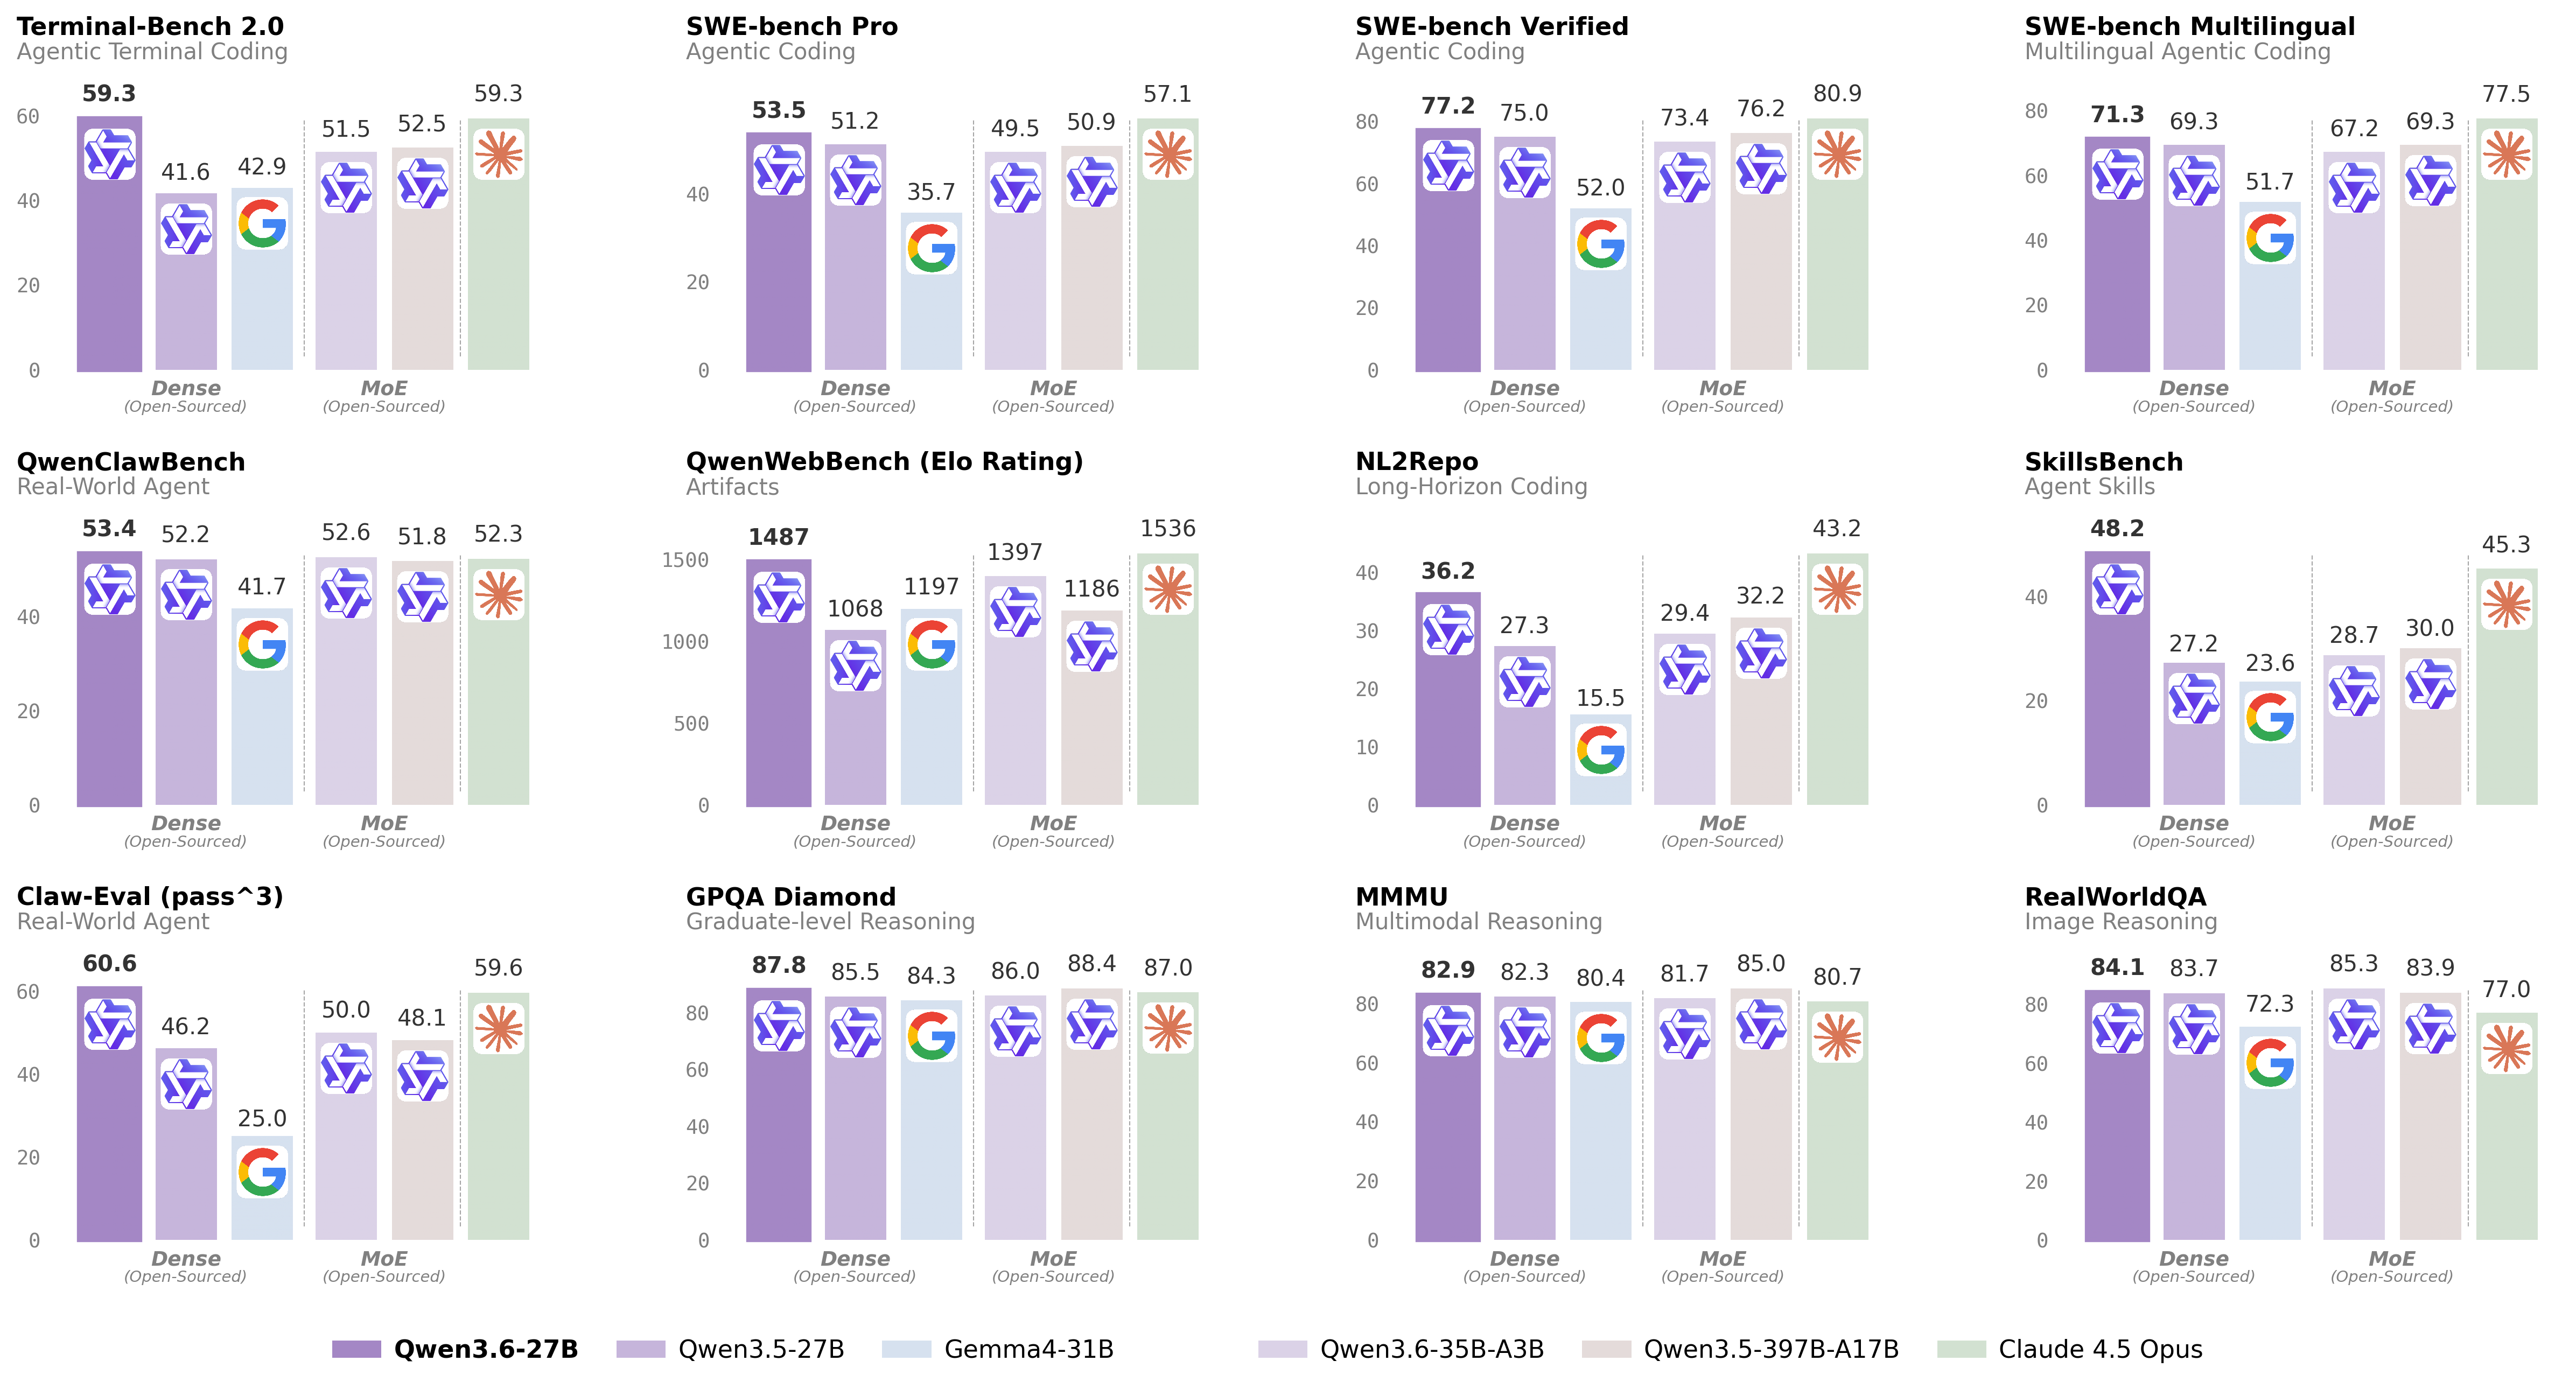
Empero's Qwen3.8 distillation into Qwen3.6-35B-A3B has 35B total parameters and about 3B active per token. This Q5_K_M GGUF build uses the embedded reasoning template and includes the F16 vision projector. Vision is inherited from the base and was not evaluated by the publisher.

Repository: localaiLicense: apache-2.0

qwen3.8-35b-a3b-distill-q8
Empero's Qwen3.8 distillation into Qwen3.6-35B-A3B has 35B total parameters and about 3B active per token. This Q8_0 GGUF build uses the embedded reasoning template and includes the F16 vision projector. Vision is inherited from the base and was not evaluated by the publisher.

Repository: localaiLicense: apache-2.0

occamy-1.0-q4
Occamy-1.0 is a 35B MoE model with 3B active parameters, based on Qwen3.6-35B-A3B and trained for multi-step agent tasks and coding. This Q4_K_M GGUF build includes the F16 vision projector and uses the embedded Jinja chat template with an 8K-token default context. Normalize prompt text to Unicode NFC to match the source tokenizer.

Repository: localaiLicense: apache-2.0

occamy-1.0-q8
Occamy-1.0 is a 35B MoE model with 3B active parameters, based on Qwen3.6-35B-A3B and trained for multi-step agent tasks and coding. This Q8_0 GGUF build includes the F16 vision projector and uses the embedded Jinja chat template with an 8K-token default context. Normalize prompt text to Unicode NFC to match the source tokenizer.

Repository: localaiLicense: apache-2.0

qwen3.6-35b-a3b-genesis-hermes-v7
Qwen3.6-35B-A3B Genesis Hermes V7 is LuffyTheFox's Apache-2.0 multimodal, agentic derivative of HauhauCS's uncensored Qwen3.6-35B-A3B model. It combines Genesis tensor calibration with Hermes function-calling data while retaining the 35B mixture-of-experts architecture, roughly 3B active parameters per token, and the native 262K-token context window. This entry's own payload uses the model card's recommended APEX GGUF and the shared F16 multimodal projector. Automatic variant selection may instead choose Compact APEX, an MTP-enabled APEX build, or Q8_K_P based on serving features and available memory. The model card recommends Jinja chat templates and at least a 128K context for its thinking behavior.

Repository: localaiLicense: apache-2.0

qwen3.6-35b-a3b-genesis-hermes-final
Qwen3.6-35B-A3B Genesis Hermes Final is a multimodal mixture-of-experts model with 35B total parameters and about 3B active per token. This uncensored derivative combines the HauhauCS base with Hermes function-calling data and the author's Genesis weight processing. This build uses APEX and includes the F16 vision projector.

Repository: localaiLicense: apache-2.0

qwen3.6-35b-a3b-genesis-hermes-final-apex-compact
Qwen3.6-35B-A3B Genesis Hermes Final is a multimodal mixture-of-experts model with 35B total parameters and about 3B active per token. This uncensored derivative combines the HauhauCS base with Hermes function-calling data and the author's Genesis weight processing. This build uses APEX Compact and includes the F16 vision projector.

Repository: localaiLicense: apache-2.0

qwen3.6-35b-a3b-genesis-hermes-final-mtp-apex
Qwen3.6-35B-A3B Genesis Hermes Final is a multimodal mixture-of-experts model with 35B total parameters and about 3B active per token. This uncensored derivative combines the HauhauCS base with Hermes function-calling data and the author's Genesis weight processing. This build uses APEX and includes the F16 vision projector. Native multi-token prediction is enabled for speculative decoding.

Repository: localaiLicense: apache-2.0

qwen3.6-35b-a3b-genesis-hermes-final-mtp-apex-compact
Qwen3.6-35B-A3B Genesis Hermes Final is a multimodal mixture-of-experts model with 35B total parameters and about 3B active per token. This uncensored derivative combines the HauhauCS base with Hermes function-calling data and the author's Genesis weight processing. This build uses APEX Compact and includes the F16 vision projector. Native multi-token prediction is enabled for speculative decoding.

Repository: localaiLicense: apache-2.0

qwen3.6-35b-a3b-genesis-hermes-final-q8-k-p
Qwen3.6-35B-A3B Genesis Hermes Final is a multimodal mixture-of-experts model with 35B total parameters and about 3B active per token. This uncensored derivative combines the HauhauCS base with Hermes function-calling data and the author's Genesis weight processing. This build uses Q8_K_P and includes the F16 vision projector.

Repository: localaiLicense: apache-2.0

qwen3.6-14b-a3b-fablevibes
Qwen3.6-14B-A3B-FableVibes is an Apache-2.0 mixture-of-experts reasoning model distilled from Fable 5 and Claude Opus traces, with additional tool calling and coding data. It retains Qwen 3.6 vision support while pruning the 35B-A3B base to a 14B consumer-oriented footprint. This default entry uses the recommended Q4_K_M GGUF quantization and its Q8_0 multimodal projector.

Repository: localaiLicense: apache-2.0

qwen3.6-27b-fable-fusion-711-uncensored-heretic-nm-dau-neo-max-mtp
Important: This is the first fine tune to exceed 700 "arc-c" (The OpenAI, Claude and Gemini "zone of intelligence") in both 8 bit and 4 bit. This repo contains both "regular" and "MTP" Neo MAX Imatrix quants. Qwen3.6-27B-Fable-Fusion-711-Uncensored-Heretic-NM-DAU-NEO-MAX-MTP-GGUF The strongest, smartest open source multi-stage model fine tune for consumer hardware ever and BUILT on consumer hardware via Unsloth. The first model of this size/type to breach "700" ARC-C in both 8 bit and 4 bit; hench the "711" in the name. This model (both 4 bit and 8 bit) exceeds the base Qwen 3.6 27B in 6 out of 7 benchmarks, and matches it on the 7th AND exceeds all 7 benchmarks for Qwen3.6-35B-A3B. The 700 "intelligence club" is reserved for OpenAI, Claude and Gemini closed source models. This is the one they fear. This is a multi-stage fine tune, multi-fine tune, and multi-stage merge. A Colab between myself (multiple fine tunes, including multi-stage), Nightmedia (merge/benching), TeichAI (Polaris Dataset), armand0e (Light fable 5 traces) and trohrbaugh (heretic'ing the model). ...

Repository: localaiLicense: apache-2.0

Page 1